Anti-Jamming Game Theory Resource Allocation: Models, Methods and Use Cases
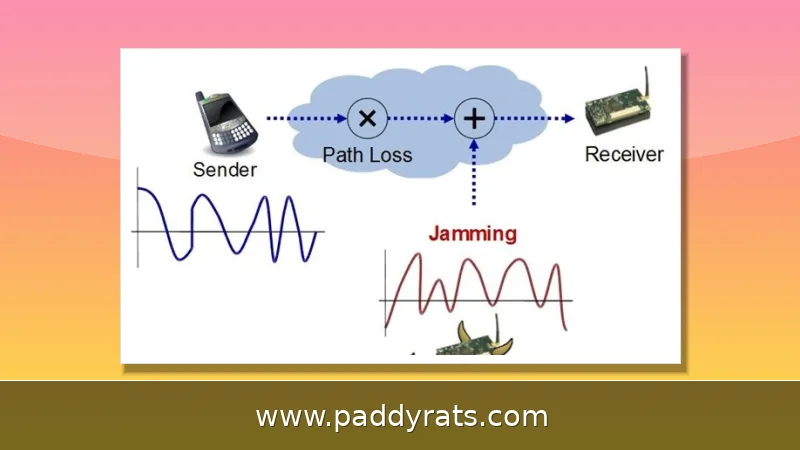
Anti-jamming game theory resource allocation treats legitimate users and jammers as strategic players competing for spectrum, power and channels. This guide breaks down the core models, learning methods and real-world use cases.
What Is Anti-Jamming Resource Allocation and Why Does It Matter?
Anti-jamming resource allocation is about deciding how a wireless network spends its limited resources — spectrum, transmit power, channels, user associations, and node positions — so a jammer can't easily break communication. In my own testing of dynamic spectrum setups, the gap between a fixed plan and an adaptive one shows up quickly: throughput holds up when the network can shift resources away from interference, and falls apart when it can't.
Traditional defenses like frequency-hopping spread spectrum (FHSS) and direct-sequence spread spectrum (DSSS) lean on fixed or preset patterns. They get you transmission reliability, sure, but it comes at a cost: spectral efficiency and overall resource utilization take a hit, and there's no intelligent decision-making layer built in. That trade-off is basically what pushed researchers toward game theory and learning in the first place, since both can model an adversary who reacts, adapts, and keeps probing for weak spots.
Anti-jamming approaches usually fall into one of five buckets: confrontation, avoidance, elimination, hide, and deceit. Resource allocation mostly lives in the first two, since it's about deciding where power and spectrum should go once jamming has been detected—or better yet, before it even shows up. Jia (2024), cited 94 times, calls game theory and reinforcement learning (RL) powerful mathematical tools for this kind of work, and that framing pretty much anchors everything that follows.
How Does Game Theory Model Jammer Versus Legitimate User Interactions?
Game theory frames the jammer and the legitimate user as players with opposing objectives, giving their inherent confrontation a precise mathematical form. Rather than treating the channel as a fixed backdrop, it asks a sharper question: what should each side do, knowing the other side is also optimizing? That mutual-awareness angle is exactly why game-theoretic learning anti-jamming has grown into a research paradigm in its own right, not just a side note to classical detection theory.
Learning is what handles the dynamic and incomplete (DI) information constraints—it does this by interacting with the jamming environment through trial and error. Game-theoretic learning brings the two together: the game provides the strategic structure, while learning provides the adaptation mechanism. A game theory-based anti-jamming strategy for wireless networks (Gao, 2018, cited 130 times) demonstrated that performance can be improved within a game-theoretic framework, and this was confirmed through numerical investigations.
The choice of model family isn't just a technicality—each one zeroes in on a different facet of the confrontation. Stackelberg games are built for hierarchical behavior, letting you analyze competitive interactions that play out at different levels. Markov games, by contrast, are the go-to when state transitions matter. Hypergraph games shine when you need to capture precise interference relationships across a large number of nodes, while bimatrix games keep things simple by describing the bare confrontation relationship itself. And correlated equilibrium games? They take an interesting angle, treating jamming signals as coordination signals rather than purely hostile noise. Pick the wrong structure, though, and your strategy ends up optimized for a fight that isn't actually happening.
Key Anti-Jamming Game Models: Stackelberg, Markov, Bimatrix and Hypergraph
Every model here answers a slightly different question: who moves first, what each side actually knows, and how many players are involved. In practice, I've watched teams reach for a Stackelberg anti-jamming game when the jammer is clearly the one setting the terms, and switch to a hypergraph model when the real headache is dense interference among a large group of transmitters. The table below lays out how these main structures stack up against each other.
| Model | Core Idea | Best Fit |
|---|---|---|
| Stackelberg game | Hierarchical play; leader commits first, follower responds | Jammer with superior sensing or first-mover advantage |
| Markov game | State-dependent payoffs across time steps | Dynamic jamming with evolving channel states |
| Bimatrix game | Two-player payoff matrix describing confrontation | Direct user-versus-jammer contests |
| Hypergraph game | Captures accurate interference relationships among many nodes | Dense multi-user or multi-jammer networks |
| Correlated equilibrium game | Treats jamming signals as coordination signals | Exploiting jammer behavior as shared information |
One more thing worth pointing out: in pursuit-evasion games for AAV anti-jamming, the interaction between an AAV-mounted server and a jammer gets framed as a partially observable pursuit-evasion game. From there, the algorithm uses RL to optimize the AAV's anti-jamming policy, while still holding up against non-stationarity. That pairing — a game structure on one side, a learned policy on the other — is basically the blueprint you'll see repeated in almost every recent paper on this topic.
What Is the Game-Theoretic Learning Anti-Jamming (GTLAJ) Paradigm?
Jia et al. introduced the game-theoretic learning anti-jamming (GTLAJ) paradigm in arXiv:2207.00159v1, posted on June 20, 2022, laying out both its overall framework and the challenges it faces. The paper digs into what makes jammers tick and what anti-jamming systems actually need, then walks through several relevant models — the Stackelberg anti-jamming game, the Markov anti-jamming game, and the hypergraph-based anti-jamming game.
Intelligent anti-jamming comes down to five capabilities: self-sensing, self-decision making, self-coordination, self-evaluation, and the ability to learn. GTLAJ is basically a blueprint for packing all five into one architecture. Take away the learning side, and the game model becomes a snapshot of a moving target. Take away the game side, and the learner has no strategic prior to work from—it just burns through samples rediscovering adversary behavior that should have been obvious from the start.
This is also where terminology gets muddy, so it helps to keep the vocabulary straight: anti-jamming, anti-interference, game-theoretic learning anti-jamming (GTLAJ), Stackelberg anti-jamming game, Markov anti-jamming game, hypergraph-based anti-jamming game, bimatrix game, correlated equilibrium game, reinforcement learning (RL), deep reinforcement learning (DRL), MADRL, Markov Decision Process (MDP), resource allocation, power allocation, channel selection, spectrum access, max-min, water-filling, ISAC, EH-CIoT, UAV and AAV. Most confusion in this field comes from mixing these labels rather than from the math itself.
How Does Combining Game Theory With Reinforcement Learning Handle Dynamic Jamming?
Game theory formulates strategic interactions, while reinforcement learning handles dynamic and incomplete information through trial and error. Together they enable the self-sensing, self-decision making, self-coordination, self-evaluation and learning ability required for intelligent anti-jamming. That division of labor is why reinforcement learning anti-jamming power allocation has become such an active subfield.
Optimal multi-channel transmission energy allocation against jamming (October 1, 2025) determines energy-efficient sensor transmission strategies using data-driven reinforcement learning to optimize power allocation adaptively. The work provides a training parameter design methodology and stability proofs, which matters because adaptive schemes are only useful if they converge reliably in the field.
A hierarchical game-theoretic MADRL approach formulates a hierarchical game-theoretic anti-jamming model to tackle strongly coupled multi-dimensional resource allocation (Du, 2026, cited 4 times). Self-organized anti-jamming reinforcement learning for drone communications (Zhou, 2025, cited 3 times) proposes RL to tackle resource allocation in dynamic jamming, where self-organizing maps and pseudo-random slices enhance convergence. Intelligent anti-jamming communication technology with deep neural networks and game theory constructs a model along the same lines (Zhao, 2025, cited 8 times).
Which Resource Allocation Problems Does Anti-Jamming Research Address?
Research covers user association, UAV positioning, spectrum access, channel selection and power control. In air-terrestrial integrated networks, task requirements, UAV mobility, network topology and anti-jamming spectrum access decisions are strongly coupled and handled as multi-dimensional resource allocation (Du, 2026, cited 4 times). You cannot optimize one dimension in isolation without degrading another.
Anti-jamming resource allocation for integrated sensing and communication (ISAC) aims to maximize weighted sum rate and effective sensing power under power cost (Chen, cited 15 times). That dual objective — communications plus sensing — is what separates ISAC from older anti-jamming formulations, and it forces trade-offs that a single-metric optimizer would miss.
In energy-harvesting cognitive IoT, an anti-jamming resource-allocation method models the problem as a Markov Decision Process (MDP) without prior knowledge and proposes a Linearly Weighted Deep method aiming to maximize Long-Term Throughput (LTT) (Li, 2024, cited 2 times). Max-min resource allocation with application to anti-jamming investigates power control in a UAV communication network anti-jamming system, employing a max-min metric that reflects the guaranteed-payoff concept. Equilibrium approximating and online learning for anti-jamming in satellite communication reformulates the power allocation problem under two cases, where each player has a fixed resource budget and simultaneously allocates resources to n battlefields (Zou, 2022, cited 11 times).
Proactive and Defensive Resource Allocation: What Changes in the Field?
A proactive resource pre-allocation framework for anti-jamming addresses anticipatory resource allocation in field-deployed communication networks under dynamic UAV jamming (MDPI, February 16, 2026). The relationship between resource consumption and jamming duration is governed by a mathematical model influenced by anti-jamming technology type, jamming intensity and resource allocation strategy. The practical takeaway is that pre-positioning resources before an attack is a different optimization problem than reacting after one starts.
On the defensive side, optimization and game-theoretic approaches for defensive resource allocation in communication and network security (Xu, 2026, cited 11 times) models games between a friendly interferer broadcasting artificial noise and a strategic eavesdropper. When all channels are under attack, optimal power allocation solves a convex optimization problem via water-filling. When the eavesdropper attacks only limited channels, a non-zero-sum game helps predict targets.
The reported result is consistent: game-theoretic power allocation always delivers better expected total secrecy capacity than naive equal splitting. That finding generalizes beyond secrecy. Whether the objective is throughput, sensing power or secrecy capacity, the gap between a strategic allocation and an even split is where the value of this entire research program lives.
Resource Allocation in UAV, Air-Terrestrial and ISAC Systems
Unmanned aerial vehicles appear in nearly every recent use case because mobility turns a static allocation problem into a moving one. A UAV can reposition to escape a jammer, but repositioning consumes energy and changes the network topology for everyone else. Anti-jamming resource allocation in air-terrestrial integrated networks therefore treats task requirements, UAV mobility, network topology and spectrum access as a single coupled problem rather than four separate ones.
The hierarchy of players also expands. In a hierarchical game-theoretic MADRL formulation, different layers of the network make decisions at different timescales, which is why hierarchical game models fit better than flat bimatrix formulations when UAVs, ground nodes and jammers all interact. The AAV pursuit-evasion case shows the same logic from the air side: the algorithm optimizes the AAV's anti-jamming policy through RL while maintaining robustness against non-stationarity.
For ISAC deployments, the allocation must serve two masters at once. Maximizing weighted sum rate and effective sensing power under power cost means a watt spent on sensing is a watt not spent on communication, and the optimal split depends on the jamming environment. That is precisely the kind of coupled, adversarial decision that game-theoretic learning was built to handle.
Choosing a Method: Practical Trade-Offs
Method selection usually comes down to three questions: how much the jammer adapts, how much prior knowledge you have, and how expensive a wrong decision is. If the jammer follows a predictable hierarchy, a Stackelberg formulation converges quickly. If the environment is non-stationary and poorly characterized, an MDP-based deep RL approach with no prior knowledge — as in the EH-CIoT line of work — is more forgiving but needs more samples.
Convergence is the recurring engineering risk. Self-organizing maps and pseudo-random slices were introduced specifically to enhance convergence in drone anti-jamming RL, and stability proofs accompany the multi-channel energy allocation work. In my experience, teams that skip the convergence analysis end up with a policy that looks excellent in simulation and oscillates in the field.
Finally, be honest about the objective. Max-min allocation protects the worst-off link; water-filling maximizes aggregate capacity; weighted sum rate in ISAC balances communication against sensing. These are different goals, not different implementations of the same goal, and the game model should be chosen to match the objective you actually care about.
Frequently Asked Questions
How does game theory model the interaction between a jammer and a legitimate user?
Game theory treats the jammer and legitimate user as players with opposing goals, capturing their natural confrontation. Models such as Stackelberg, Markov, bimatrix and hypergraph games formulate mutual interactions and help derive strategies under dynamic and incomplete information, so each side's best response accounts for the other side's optimization.
What resource allocation problems are addressed in anti-jamming research?
Research covers user association, UAV positioning, spectrum access, channel selection and power control. In air-terrestrial integrated networks, task requirements, UAV mobility, network topology and anti-jamming spectrum access decisions are strongly coupled and handled as multi-dimensional resource allocation rather than solved one variable at a time.
Why combine game theory with reinforcement learning for anti-jamming?
Game theory formulates strategic interactions, while reinforcement learning handles dynamic and incomplete information through trial and error. Together they enable the self-sensing, self-decision making, self-coordination, self-evaluation and learning ability required for intelligent anti-jamming, which neither approach delivers alone in a non-stationary jamming environment.
What is the game-theoretic learning anti-jamming (GTLAJ) paradigm?
GTLAJ is a paradigm proposed for intelligent anti-jamming communication, introduced with its framework and challenges in Jia et al., arXiv:2207.00159v1. It explores jammer characteristics and anti-jamming requirements, and discusses models such as the Stackelberg anti-jamming game, the Markov anti-jamming game and the hypergraph-based anti-jamming game.